Getting to the real problemDeciding with evidenceFinding the swingLeading through uncertainty
When the research disagrees with the roadmap.
Three months after launch, growth had flatlined. What users told us contradicted what we'd shipped — and the job became finding the right direction, fast.
Role
Founding Product & Research Lead
Timeline
Jan 2026 – present First launch: Mar 2026 Pivot: mid-2026 New direction live: Aug 2026
Team
6-person product team design · growth · research
Traction · Sep 2026
1,300+ registered golfers 11 signed PGA coaches AI-report adoption 32→56%
The short version
What we launched
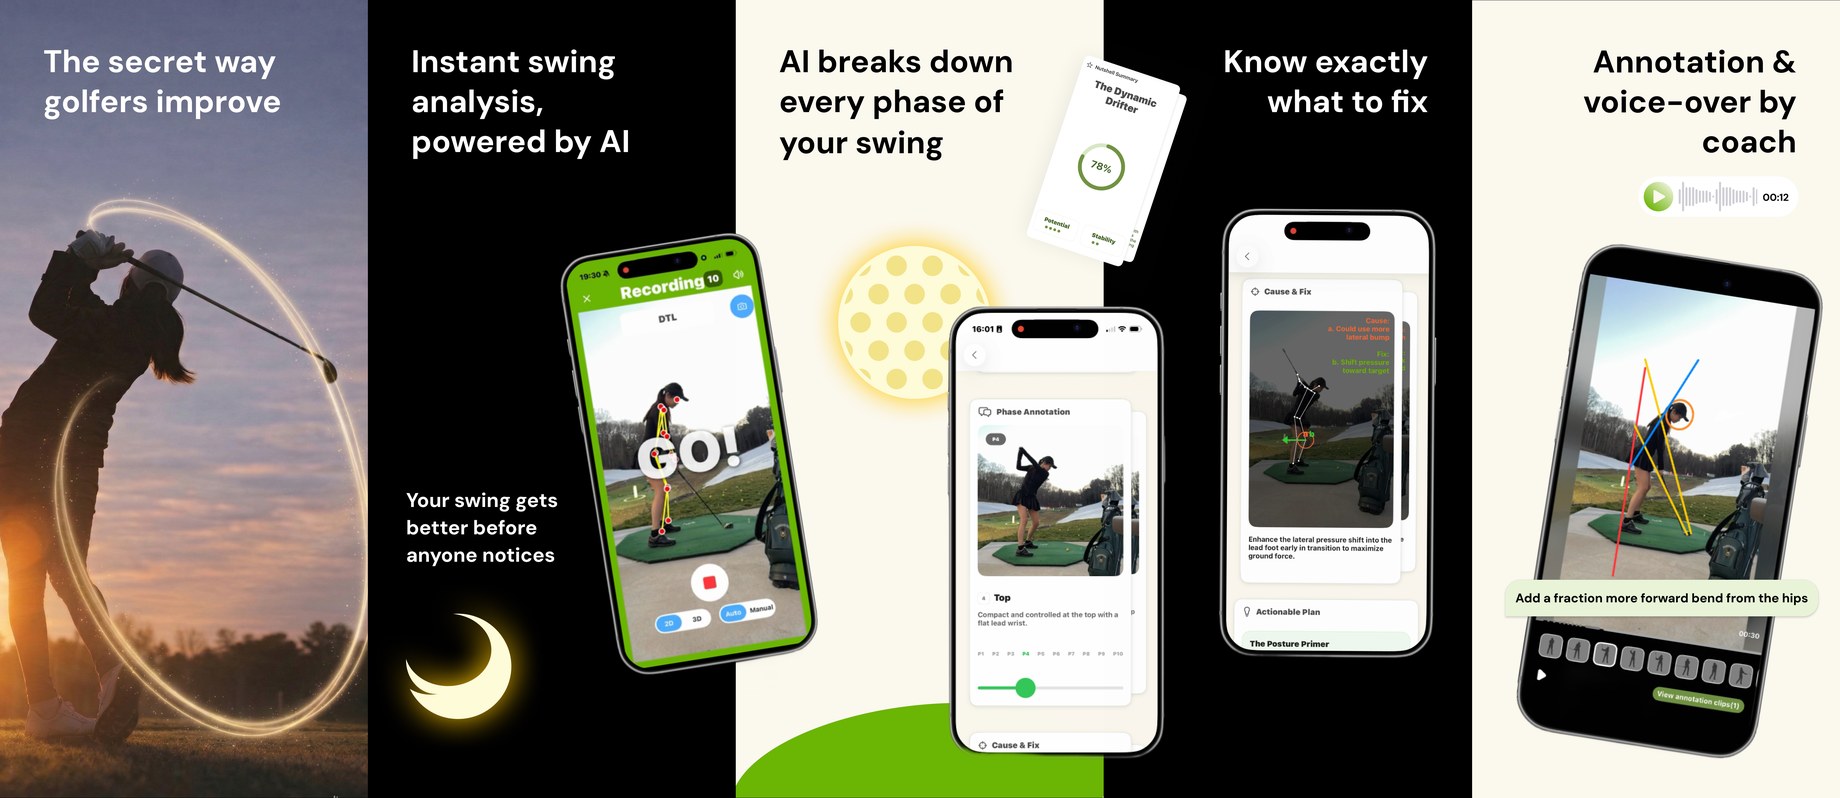
SneakySwing: “a coach in your pocket” — an AI digital twin of a golfer's own coach. B2B2C: coaches on one side, golfers on the other.
What went wrong
Three months in, growth was flat and investors said the scale wasn't there. The coach side worked. The golfer side was the hole in the boat.
What I found
Golfers don't want an AI coach. To them, an AI coach is just a worse coach. What they'd pay for is a practice partner good enough to trust — validated by their real coach.
What changed
Repositioned to “the coach's copilot × the golfer's practice companion”, rebuilt how AI and coach divide the work, and reframed the company's scale story from a golf app to a portable record of how a person moves and learns.
01
Three months in, the line was flat
Perflection AI builds motion analysis for golf. We'd shipped SneakySwing on a B2B2C model — coaches on one side, their students on the other — with a promise to golfers we were proud of: a coach in your pocket. Distil a coach's expertise, build an AI digital twin, and let it analyse your swing whenever you practise.
Three months after launch, growth hadn't moved and investors were telling us the scale wasn't big enough. Inside the company, two readings were on the table: we hadn't marketed hard enough, or we'd built something people don't want.
Those two diagnoses point the company's resources in opposite directions — one spends on reach, the other on rebuilding the product. So I went to find out which one was true.
02
Half the product was working. Half of it wasn't.
✓Coach side
Solving a real problem
Coaches don't only teach — they run a business. We weren't just doing scheduling; we were integrating each student's learning profile so a coach could see who's who and how they're progressing. That value proposition held up.
✕Golfer side
Full of holes
The golfer value proposition didn't survive contact with users. And no golfers using the product means coaches have nobody to push it to — the loop can't close.
The argument that decided it
We could have retreated into being a student CRM for coaches. But our differentiation is that we don't just manage lessons — we connect a student's learning state, history and individual needs. Without the golfer side, there is no differentiation and no loop. Fixing it wasn't optional.
03
“An AI coach is just a worse coach”
Across interviews, the same thing kept coming back — and it went directly against the product we had shipped.
Golfers don't want an AI coach. To them it's a second-rate coach — it will never beat a real one.
The wallet agreed with the sentiment: when AI analysis wasn't meaningfully better than the free tools already on their phone, nobody paid for it.
But they weren't saying they didn't need help. What they described wanting was specific — and it wasn't a coach substitute:
Right nowFeedback during practice, not a report afterwards
My problemA focus they set themselves, not a template
Did it work?Confirmation the fix actually landed
The reframe
Their core need was never new knowledge — it was validation and trust. They already know what they're supposed to fix. What they can't tell, alone on a range, is whether they just did it right. Several said plainly: they'd trust the AI once their own coach had validated it.
Which meant the thing we'd built — a machine that tells you what's wrong — was answering a question nobody was stuck on.
04
What we built instead
We talked to 20+ golfers and 6 coaches, and read 5+ competing products against each other. What came back wasn't two wish-lists. It was one blind spot both sides shared: the practice nobody is there for.
A golfer sees their coach for an hour a week. For plenty of them it's an hour a month. So 99% of the time the two of them are not in the same place — and that 99% is where the swing actually gets built, or quietly broken.
This is the 1% — the time a coach and a student are actually in the same room. What we were building had to work in the other 99%, after they leave.
A copilot for the relationship — less work for the coach, and a golfer who feels more seen.
That created a hard design problem: how do you use AI heavily without letting it replace the coach? The answer turned out not to be a better model. It was deciding what counts as agreed — and building the thing that decides it.
Scroll to see the whole pipeline →
Three conversations feed the system: the golfer alone with the AI, the shared room where golfer and coach both talk, and the coach's own feedback. Nothing in them is adopted on the AI's say-so. Every statement is typed, logged against a shared vocabulary, and then it waits — a self-report becomes a goal only once the golfer confirms it, and the issue pool becomes a goal only once the coach has edited it and set one. The system never concludes anything by itself.
Where the two sides disagree, there is a rule rather than a guess: the coach's judgement takes precedence. Their instruction and feedback override the golfer's own goal in the current focus — the thing that decides how the AI reads the next session. The golfer's goals aren't deleted; they're outranked by the person the golfer came here to learn from.
That's where the trust comes from, and it isn't the model. Everything the AI says next traces back to something a real person wrote down and a real person approved. Neither human is being automated — they are the two who decide what the system treats as true, and the AI does the noticing, sorting and remembering in between.
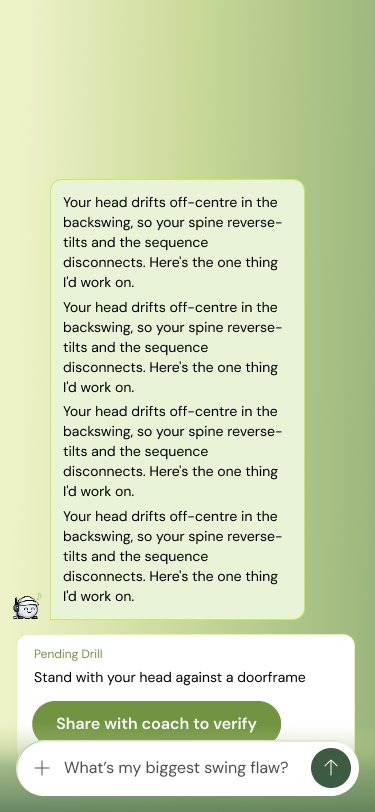
The golfer decidesAI proposes a drill and stops there. Nothing reaches the coach until the golfer sends it to be verified.
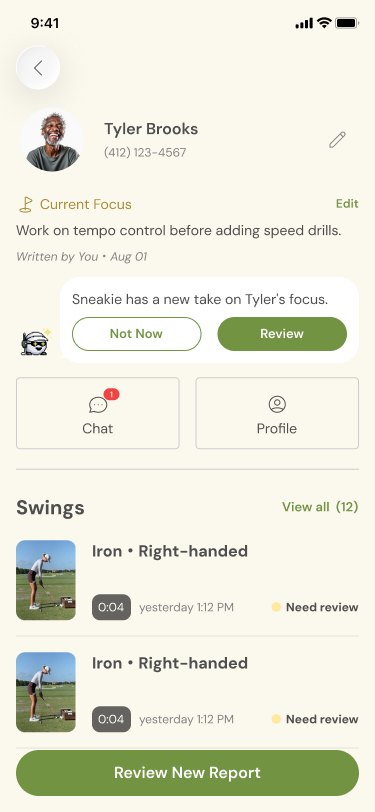
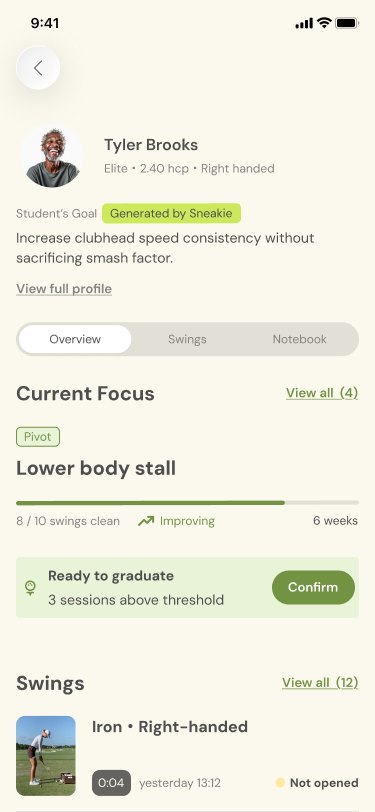
The coach decidesThe AI can suggest a new focus. It cannot set one — the current focus still reads “Written by You”.
Both sides read the same recordGoal, current focus, progress, and whether the feedback was ever opened — one page, not two versions of the truth.
What the coach is actually buying
Coaches don't divide by skill. They divide by how they hold a roster — and the two kinds end up wanting the same thing for opposite reasons.
High volume
Relationship as a cost
More students than a day has hours. Replying to everyone simply does not fit, so staying in touch is something to contain — and they only track who read what for their top students.
High touch
Relationship as an investment
A roster small enough to know by name, and they want to see all of it: did the feedback get opened, did the golfer practice after it. The same work compounds instead of draining.
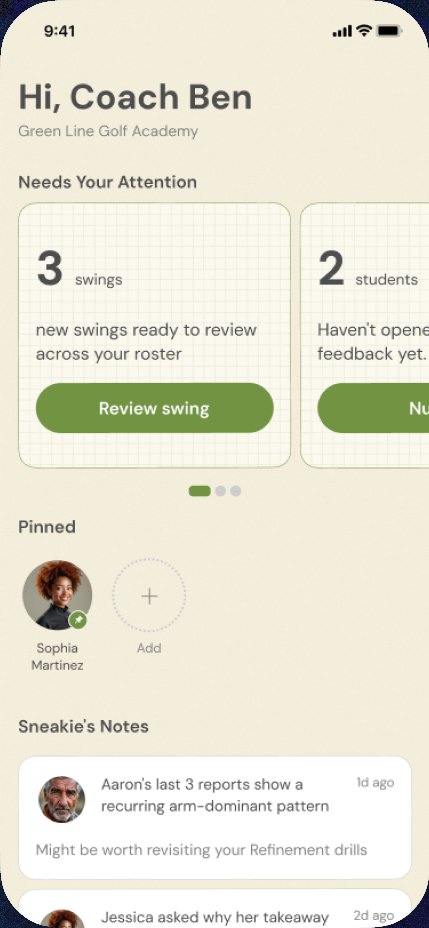
The coach's home screen is a relationship queue.Who is waiting, who never opened what you sent, and what the AI noticed across a roster you can't read one by one.
Opposite economics, one shared ask — stay present with every student, not just the ones there was time for. That is what a coach is paying for. It is also why the thing being automated here is relationship maintenance, not swing analysis: the analysis was never the scarce part.
The scarce part is being understood. Drawing a line on a video is table stakes — every coaching app does it. What coaches and golfers both asked for, unprompted, was comparison: this swing against the one from six weeks ago, or against the coach's own. That is the difference between an annotation and an explanation, and it's the feature request I heard from both sides of the marketplace.
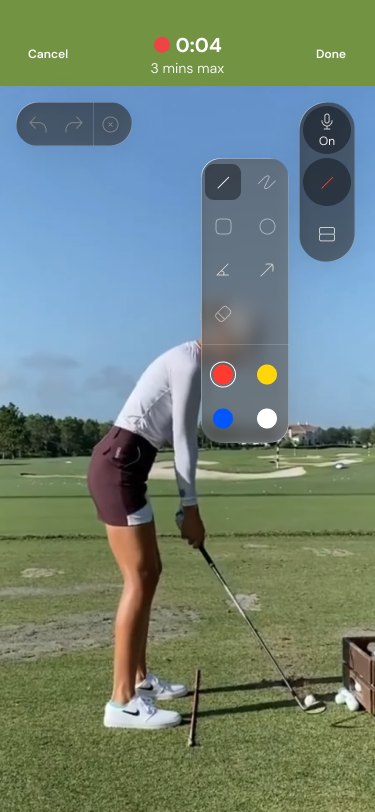
Mark it upLines, angles and a voice note straight onto the frame. This part every coaching app already has.
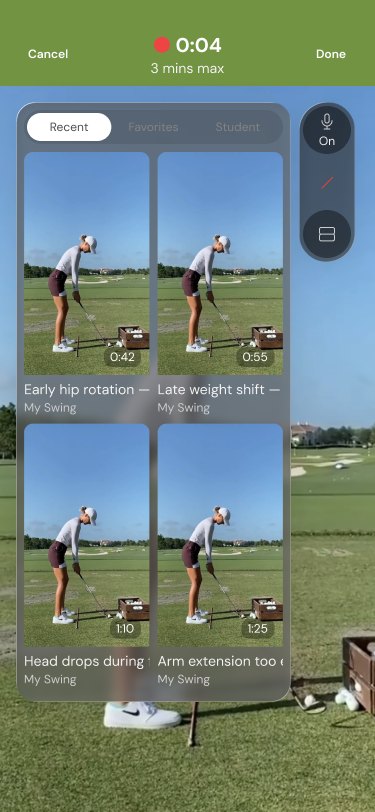
Pull up something to hold it againstThe golfer's own earlier swings, the coach's library, or the coach's own — each clip labelled with the issue it shows.
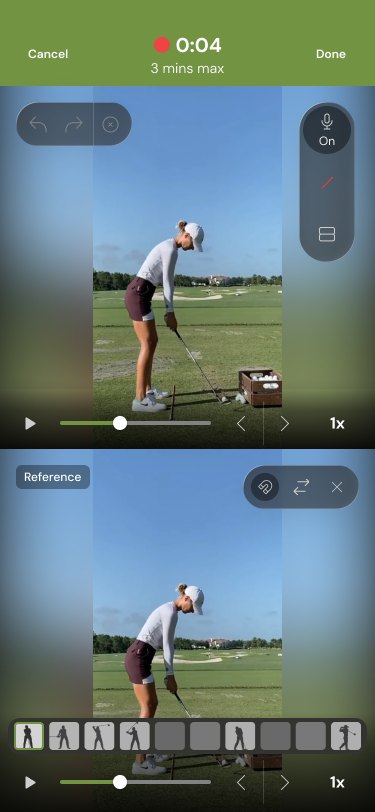
Hold both at the same momentTwo swings, one scrubber, frame by frame — so “you're doing it again” becomes something the golfer can see rather than take on trust.
One dataset, many ways to see it
The research also killed the idea that there is one right report. One golfer told us skeleton points and joint-angle charts were unreadable — “I can't tell what I'm looking at.” A tour-level coach in the same study wanted the opposite: exact pelvis and chest-turn angles, side by side with a professional's swing. Same data, opposite needs. Several were also explicit that templated analysis is actively wrong for them — bodies differ, so a one-size-fits-all read misdiagnoses.
So what we're building isn't a single interface. It's a preference model × modules × components:
Interactive — switch the preset
A working prototype of the golfer's home. The switch at the top stands in for what the preference model has learned about this person; changing it re-renders all three modules at once. Same session, same numbers, a different way of being told — a sentence, a body map or a cue card; tiles, a video comparison or bullet points; a chart, a paragraph or a set of milestones.
Preference model
Who this person is
Four questions at signup — almost everything after that is learned rather than asked.
Modules
Ways of showing
Plain-language cues, a dashboard, video comparison, trajectory lines, progress tracking — each a legitimate way to answer the same question.
Components
Pieces to assemble from
Views get composed per person rather than designed once for everyone. No two golfers get the same dashboard — each one reads the same session in the form they actually understand it in.
Progressive profiling — earn the data, don't demand it
We ask for as little as possible at the door — four questions — because a long form is where new users leave. Everything after that accumulates on its own: implicit signals from what they open and act on; small questions surfaced in the drawer while their analysis is processing, turning dead time into signal instead of a spinner; the profile they choose to fill in as they get more invested; and their coach's annotations — expert labels that feed the preference model and the analysis model at the same time.
The same session then reaches three people three different ways: a body-feel cue for one golfer, a trajectory overlay for another, precise angles for their coach. Learning a sport was never a one-size-fits-all process — so the way the information arrives can't be either.
And because preference is learned rather than hard-coded, it travels with the person — which is what makes the next part possible.
05
What it cost to be right
Repositioning sounds clean written down. It wasn't.
Once “the coach cannot be replaced” became the premise, roughly 60% of the existing roadmap and data tagging had to be reworked. Months of model work aimed at out-performing a human coach stopped being the point — the AI no longer needed to be that powerful. The hard problem moved from model accuracy to relationship and data.
Moving fast matters. Finding the right direction fast matters more.
— the position I took into that conversation
That's an expensive thing to say to a team that has been building the other thing — and it's the part of this project I'm proudest of handling. I came in as a UX researcher; I now set product direction and lead a 6-person product team across design, growth and research. The work that actually takes the time isn't the research. It's holding a direction steady across people who each see a different part of it: engineers who'd built for the old premise, designers who need decisions to be concrete, founders carrying investor pressure, and the 11 PGA coaches who'd signed on, whose trust is the product.
The reposition only stuck because each of those groups could see their own reason to believe it. Not being the person with the answer — getting everyone pointed at the same one.
06
Fast is only an advantage if you can tell when you're wrong
We ship every one to two weeks. Research that takes six weeks to answer a question is research nobody will wait for — so the real constraint on my work isn't rigour, it's keeping pace with the build.
That pace is our biggest advantage over a large company: we can be wrong far faster than they can be right. But being wrong is only cheap if you can tell that you were — quickly, and ideally before it costs a release. Two things make that possible.
One · Numbers tell you where. People tell you why.
At our scale, no number is significant on its own. That doesn't mean we don't look — we read everything; we just never let a number conclude anything by itself. Small samples don't lie, they under-determine. The risk isn't missing the signal, it's over-reading it. So nothing travels from a chart to a decision without passing through people on the way.
1 · Quant points
Where something is wrong
Flat growth. Low report adoption. A number tells you where to look — never why.
→
2 · Qual explains
Why it's wrong
Interviews surface the reason nobody wants a substitute coach. This is where the hypothesis is born.
→
3 · Quant confirms
Whether the fix worked
The reposition ships. AI-report adoption moves 32% → 56% within two months, and has held at 53–59% since.
…and the new number points at the next thing to go and ask about
Exploratory sequential · qual first, then the metric it generates
One golfer told us feedback within 2–3 seconds is useful; 10 seconds is worthless — “by then I've already hit the next ball.” A sentence in an interview became a hard acceptance threshold the engineering team now builds against. Qualitative work doesn't only explain things; it produces the numbers worth tracking.
Explanatory sequential · the number first, then the reason behind it
Willingness-to-pay surveys give you a band. Interviews tell you what people are pricing you against. One golfer capped us at $100/month, anchored on his ChatGPT and Claude subscriptions plus lesson fees. Another would pay $10–20. On a chart both read as “price sensitive.” In reality they're two different products.
Qual as measurement · a scorecard for concepts that don't exist yet
For a 0→1 product, most of what needs testing hasn't been built. So I built a scorecard for usability and concept sessions that scores whether a user actually understands the new concept and whether they'd accept it — turning a qualitative session into a number we can track across versions. “Does the new direction land?” stops being an opinion in a meeting.
Two · Stop using releases as the test
A public release is an expensive way to find out a concept doesn't land — and at a two-week cadence, that's an expensive mistake you could repeat twenty-six times a year. Trial and error only works when the error is caught somewhere cheaper. So I built the research to run on two tracks at once.
Delivery track · Evaluative
Validating what's already shipped
Benchmarked usability on live versions, scored against the same card release over release — so we can tell whether each version actually got easier, not just different.
Discovery track · Generative
Testing what doesn't exist yet
Concept testing against prototypes, before engineering commits — scored for comprehension and acceptance on what people say and what they do with it. Around that: retrospective critical-incident interviews on their last good and bad practice session, workflow and scenario mapping, and an audit of what they already reach for instead of us.
This is dual-track research: discovery and delivery running in parallel rather than in sequence. The delivery track keeps the current product honest; the discovery track keeps us from betting a roadmap on a hunch. The moment the two become sequential, you're either polishing something nobody wants or shipping something you never checked — and at our speed, either one compounds fast.
What holds both halves together is a persona system built on behaviour, not attributes — level of investment × willingness to pay × core need — with sample size and confidence attached to every segment, so we always know how much weight a finding can bear. An n=1 segment stays provisional. Nobody gets force-fit into a category to make the deck look tidy.
In a company where the product changes month to month, personas built on attributes rot on contact with a pivot. Built on behaviour, they survive one — and the team is still using them.
07
Why this isn't a golf app
Early on, the sentence that kept us out of rooms was always the same: the scale isn't big enough. Golf coaching is a small market, and about that they were right.
What I found once the new direction was set is that the most valuable thing we were building was never the golf product. A sports-science record of how a body moves and learns doesn't stop at one sport — it carries across sports, and then out of sport altogether, into clinical use.
The answer came out of the same asset thinking that fixed the product. A coach can treat a student's learning history as an asset: who practises, who improves, who deserves their scarce time. My extension was the other half — the student owns one too. They should be able to export their learning and progress state (not the coach's instruction, which stays with the coach) and carry it with them.
Once a record of how a person moves and learns is portable, the market stops being golf:
One coach → another
A golfer changes coaches without starting from zero. The new coach opens a history instead of an empty file.
One sport → another
Golf, ski, tennis. A yoga or surf instructor instantly understands how this person controls their body — and where they'll struggle.
Sport → medicine
A physio can see what caused an injury. A coach can adapt around a spinal condition they'd otherwise never know about. The training record becomes clinical context.
A dataset → sports science
Movement and learning data across people, sports and recovery — the layer underneath all of it.
Why this version of the pitch worked
It isn't a bigger number bolted onto the deck. The scale story and the product story became the same story — both come from treating the learning record as something the user owns and carries. That's the version investors leaned into, and it's the direction I've been steering the roadmap toward since: where sports science meets digital health.
08
How I know whether it's working
North star · behaviour
Co-pilot loop breadth
The share of registered coach–golfer pairs that complete at least one full loop in a rolling 14 days, counted separately for each entry point. It only moves if both sides showed up. The loop went live in August 2026, so this is still a baseline rather than a score — which is exactly why it gets defined now. Wait for a number to show up and it decides for you what success meant.
Ends inPair survival ratePairs still active at 3 and 6 months. The commercial result the north star is a leading indicator for — a loop that runs once is a demo, a relationship that lasts is a business.
DiagnosesEntry mixCoach-initiated versus golfer-initiated. Read the direction it moves, not the level — a product where only the golfer ever starts is one bad week away from silence.
This quarterQualified prescriptionsPer active coach per week: an annotation on the video plus a named drill. Picking the drill is the part you can't do without having watched.
GuardrailCoach edit rate · rejection rateHas to sit inside a band, not be maximised. Zero edits means nobody is really reviewing; sky-high means the AI isn't good enough to be worth reviewing.
InputAI drafts generated · report adoptionSupply. Adoption moved 32% → 56% and holds at 53–59% — if the AI half stops producing, nothing downstream can happen.
Guardrails — how this could fail
Over-trust. Some users believe AI unconditionally — which is why the AI gives observations and open questions, never conclusions. The coach holds the final interpretation by design.
Adoption without habit. Several interviewees rated their disappointment-if-it-vanished at 3/10. Opening a report is not the same as building a practice routine around it.
Capture quality. Everything downstream depends on a usable video. If people can't film themselves easily, the analysis degrades before it starts.
Progressive profiling creepiness. We learn preferences by asking over time. Asked too fast or too personally, a companion becomes surveillance.
09
What this one taught me
An ordinary evening at the range. Everything in this case study depends on this moment being easy.
Flat growth is a question, not a verdict. “Market harder” and “we built the wrong thing” look identical on a dashboard. The only way to tell them apart is to go and ask — and to be willing to hear the second answer.
Speed is only a virtue with a direction attached. A two-week cadence means you can be wrong twenty-six times a year, or right twenty-six times — the velocity is identical. What separates them is whether anyone checked. Moving fast is what got us to the wrong product quickly; moving fast and checking is what got us out of it.
The best product decision I made was to make our AI less ambitious. Once the evidence said the coach can't be replaced, the model didn't need to win. Sometimes the strategic move is to give the hardest part of the job away — to the human the user already trusts.
Users don't reject AI. They reject being handed a worse version of something they value. That's the sentence I'll carry into whatever I build next.